Run NVIDIA’s open multimodal model, Nemotron 3.5 Super VL, for agentic AI on reserved GPU capacity with Nscale Dedicated Inference.
We’re excited to bring NVIDIA Nemotron 3.5 Super VL to Nscale Dedicated Inference, opening up new possibilities for developers building multimodal agents that can see, reason, and act on reserved GPU capacity.
NVIDIA Nemotron 3.5 Super VL combines text, image, document, and video understanding with agentic reasoning and tool use, in a single open model.
With Nscale managing the inference infrastructure, developers can focus on building and evaluating multimodal agents rather than operating the model-serving stack themselves.
Request access to Nemotron 3.5 Super VL
Multimodal capabilities built for agentic AI
Nemotron 3.5 Super VL is an open multimodal model built for agentic applications that need to understand visual information, reason over it and use tools .
Under the hood, it uses a 120-billion-parameter Mixture-of-Experts (MoE) architecture with 12 billion active parameters, balancing model capability with inference efficiency.
What sets the model apart is how those capabilities come together. Rather than treating visual understanding, reasoning, and tool use as separate steps, the model can work across multiple forms of information as part of the same agentic workflow.
For developers, this means agents can work across the different types of information they encounter in real-world workflows. They can interpret a document, understand an interface or image, reason about what they see, and use tools to take the next action.
For specialized applications, organizations can also customize Nemotron 3.5 Super VL with NVIDIA NeMo, using their own data, tools, policies, and workflows to adapt the model to domain-specific multimodal tasks.
The model also forms part of NVIDIA’s broader open agentic ecosystem, alongside technologies such as NemoClaw and NVIDIA OpenShell, giving developers an expanding set of building blocks for creating, customizing, and running open AI agents.
The result is a model designed not simply to understand multimodal inputs, but to reason across them and use that understanding to perform real work.
Performance designed for agentic workloads
Agentic workloads place different demands on inference than a single prompt and response. Agents can operate across long-running, multi-turn workflows, repeatedly reasoning, processing new information, and using tools, making both model intelligence and inference efficiency important.
Nemotron 3.5 Super VL is designed with these workloads in mind. Its hybrid Mamba-Transformer architecture and multi-token prediction help accelerate generation, while NVFP4 KV cache quantization reduces the memory footprint of the KV cache. This creates more headroom for concurrent long-context sessions and can reduce KV cache eviction and recomputation in multi-turn agent workflows.
The model is also designed to deliver strong capability with relatively limited compute. In NVIDIA’s latest comparison of open models, it ranks among the leading models for limited-compute deployments while running on a single NVIDIA Blackwell200 GPU.
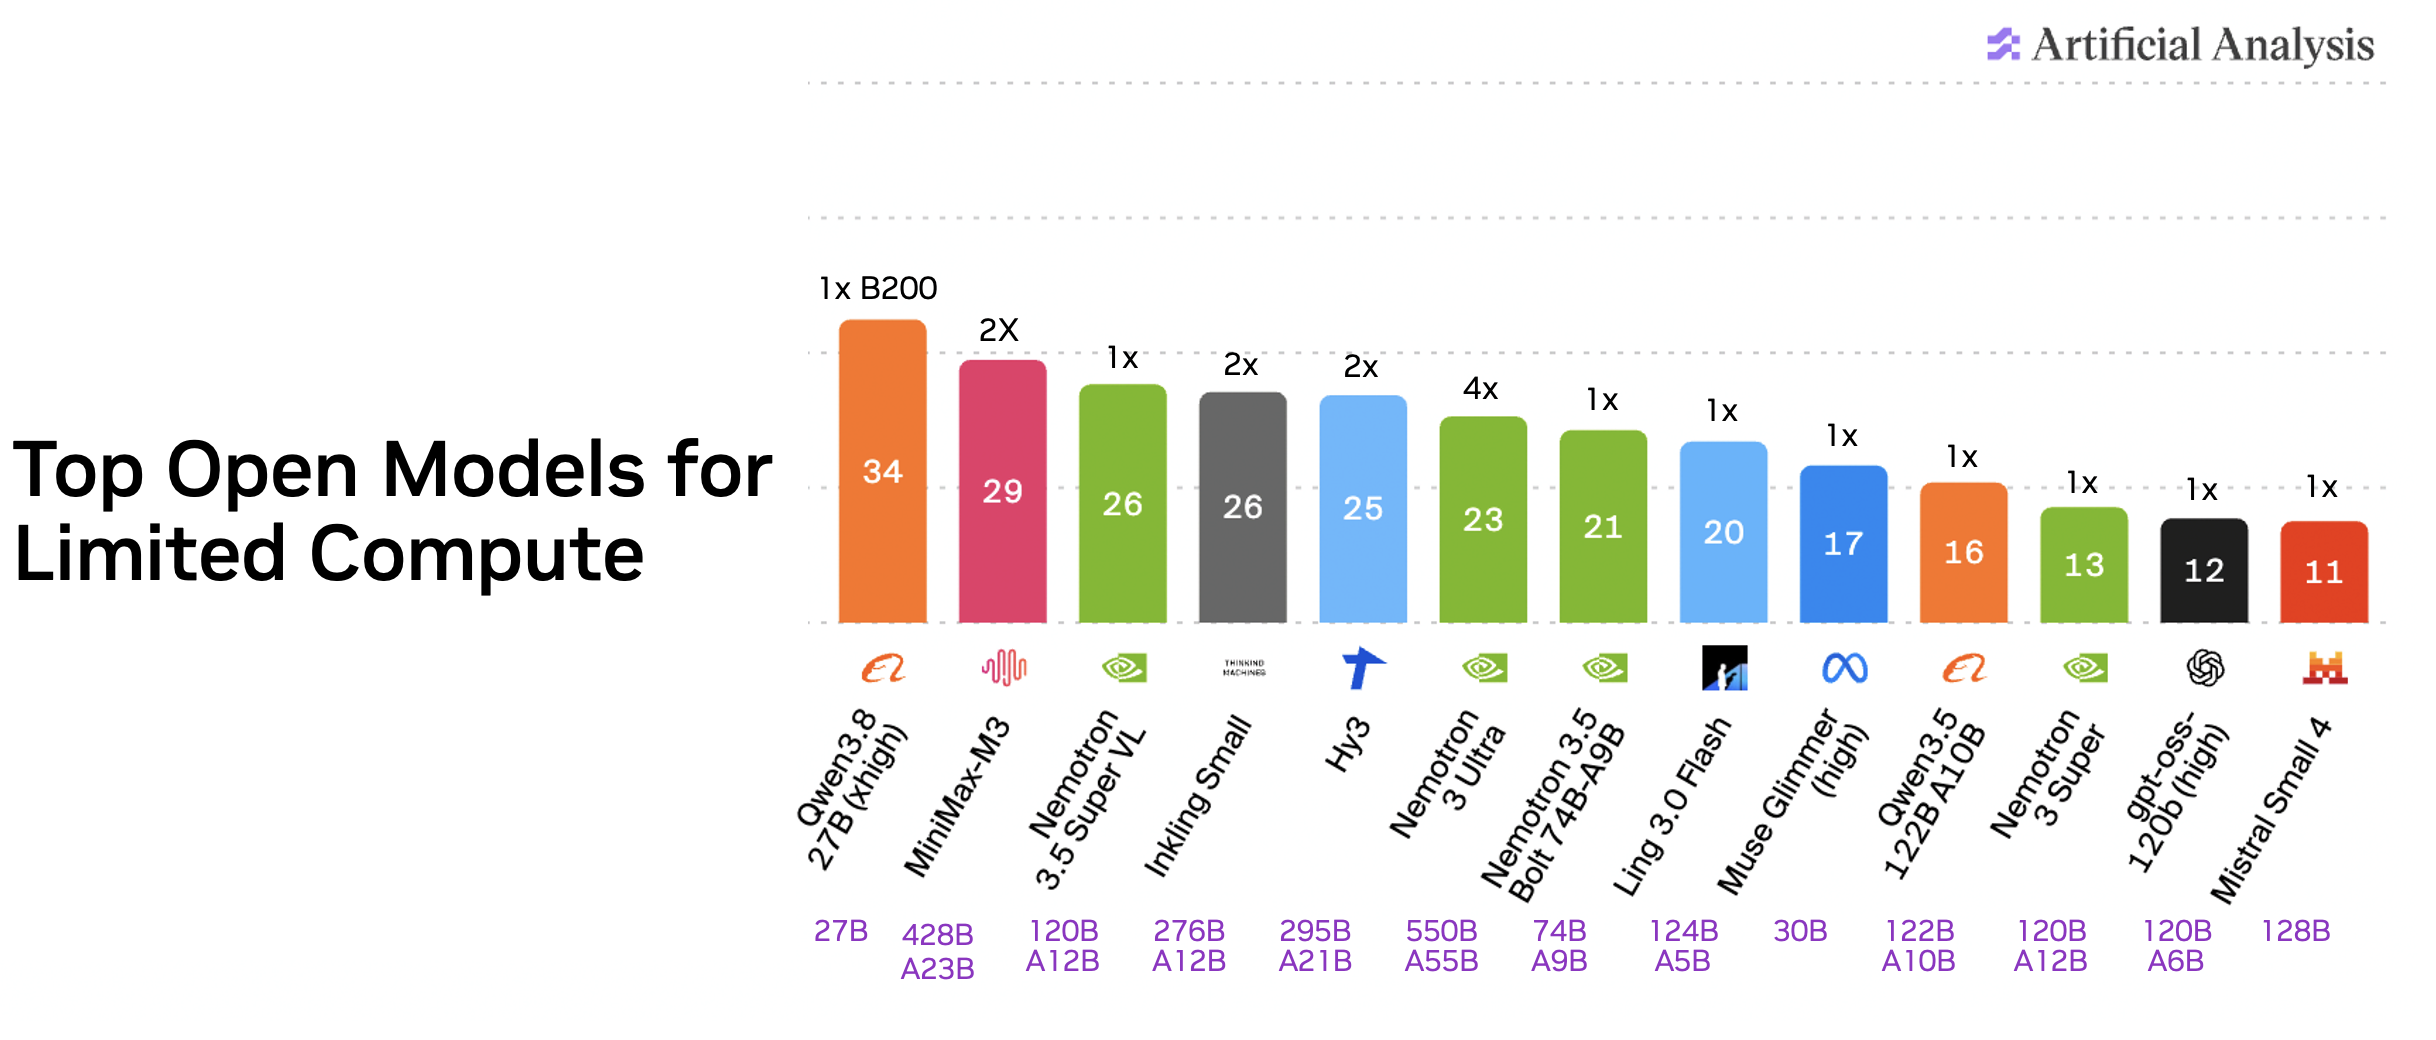
In NVIDIA’s latest agentic coding benchmarks, the model completed 10,000 tasks up to 4× faster than Qwen3.8 Flash Next on 4× NVIDIA Blackwell GPUs, while maintaining competitive SWE-Bench Pro accuracy.
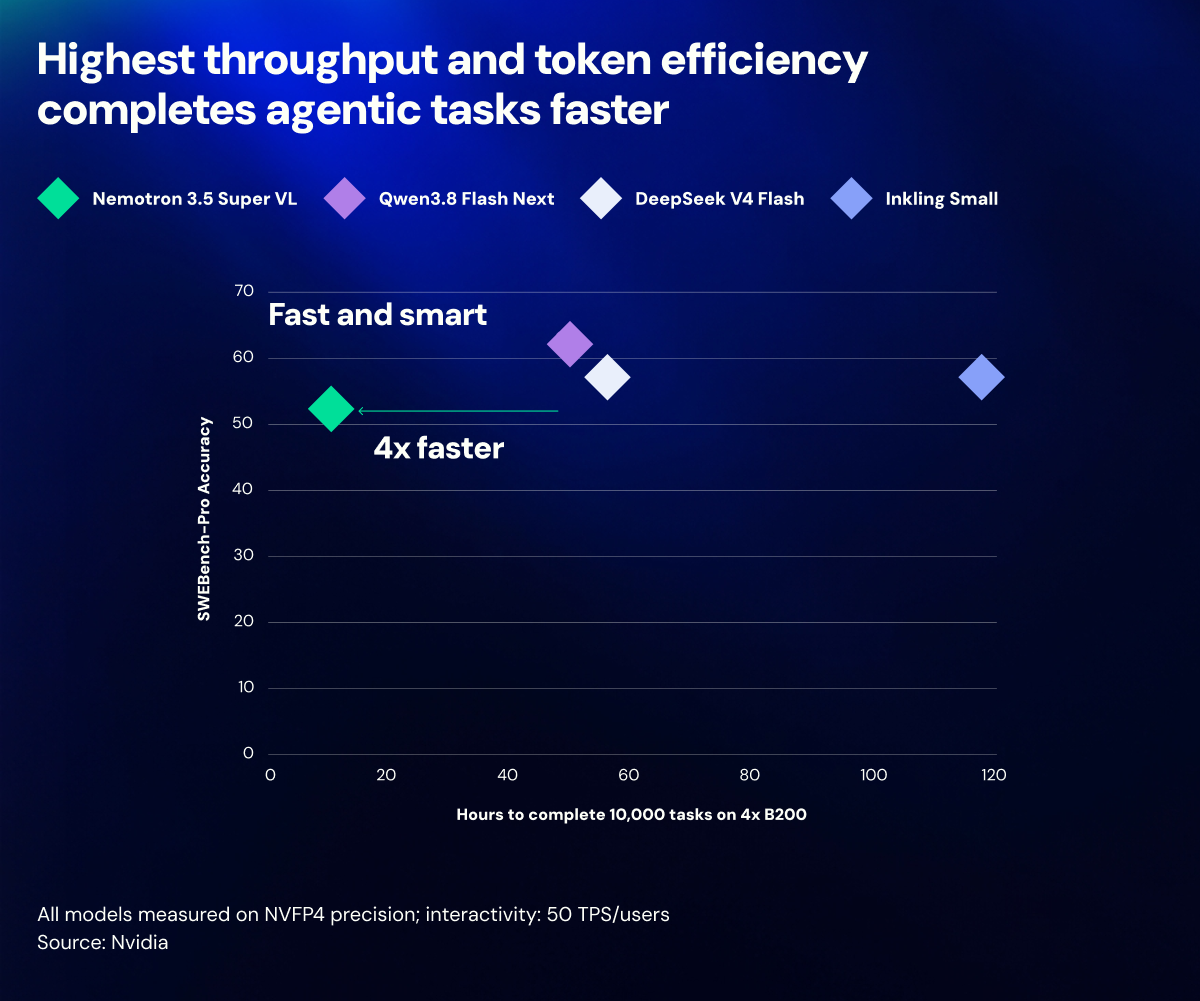
Together, these results demonstrate a combination of model capability with inference efficiency, helping developers run long-running agentic workloads with less compute and faster task completion.
From web research to code: What can you build with Nemotron 3.5 Super VL?
The combination of multimodal understanding, reasoning, and tool use opens up a wide range of applications. Here are five areas where Nemotron 3.5 Super VL particularly stands out.
1. Web research
What it does: Search across websites, connect information from multiple sources and verify results as part of longer-running research tasks.
Good for: Research agents, competitive intelligence, market analysis, knowledge discovery and automated information gathering.
2. Document intelligence
What it does: Understand complex documents containing text, images, tables, charts, and page layouts, then reason across that information to extract insights or generate structured outputs.
Good for: Enterprise knowledge systems, document processing, financial and technical analysis, report generation, and multimodal RAG workflows.
3. Customer service
What it does: Interpret customer-provided documents and images, reason against relevant policies and use service tools to complete multi-step requests.
Good for: Customer support agents, claims and case processing, troubleshooting and service automation.
4. Video understanding
What it does: Extract and reason over information contained within video.
Good for: Video search, content review, advertising, retail workflows and incident analysis.
5. Coding
What it does: Support agentic coding workflows that require reasoning and multi-step task completion.
Good for: Coding agents and software engineering workflows.
Adapt Nemotron 3.5 Super VL to your workflows
General model capability is only one part of building useful enterprise agents. Specialized applications need models that can work within the terminology, policies, tools, and workflows of a particular organization or domain.
Nemotron 3.5 Super VL is designed to support that level of specialization, giving organizations a path to build multimodal agents around their own requirements rather than relying solely on general-purpose model behavior.
Just as importantly, organizations have the flexibility to deploy across local, data center, and cloud environments, giving teams greater control over model behavior, data handling, and agent workflows.
That combination of customization and deployment flexibility gives organizations greater control over how multimodal agents are built and operated.
Why deploy Nemotron 3.5 Super VL on Nscale?
Running multimodal agents in production requires more than model access. Teams need predictable capacity, reliable serving infrastructure and control over where their workloads run.
Nscale Dedicated inference provides:
Full-stack by design. Run and scale inference through an integrated AI stack spanning infrastructure, orchestration, and AI services.
Dedicated capacity, managed inference. Nscale manages the serving layer on your reserved GPU capacity, so teams can run production inference without building or operating it themselves.
Predictable infrastructure economics. Reserved capacity gives teams greater visibility and control over the infrastructure powering their inference workloads.
Built with frontier partners. Bringing the latest AI models and technologies to Nscale from Day 0 with partners like NVIDIA.
Sovereign by default. Enable in-country deployment by design for regulated workloads and enterprise requirements.
Get started with Nemotron 3.5 Super VL on Nscale
NVIDIA Nemotron 3.5 Super VL is available on Nscale Dedicated Inference.
Once your Nscale organization is set up, you can create clusters within your dedicated capacity, deploy the model, and expose it through a private endpoint for your applications.
With dedicated capacity, your team has control over its AI workloads and the flexibility to deploy other supported models as requirements evolve.
Whether you’re building web research agents, document intelligence, customer-service automation, video understanding, or coding agents, Nscale Dedicated Inference provides a direct route from model to production.
To get started, contact our AI team to discuss your workload, GPU capacity requirements and deployment configuration.
Request access to Nemotron 3.5 Super VL
Nemotron 3.5 Super VL joins a growing collection of models available on Nscale, including GLM and DeepSeek variants. From Dedicated and Serverless Inference to Fine-tuning and Prompt Workbench, explore our full suite of AI Services.