The first systems are live, with a continued global rollout coming online in the months ahead.
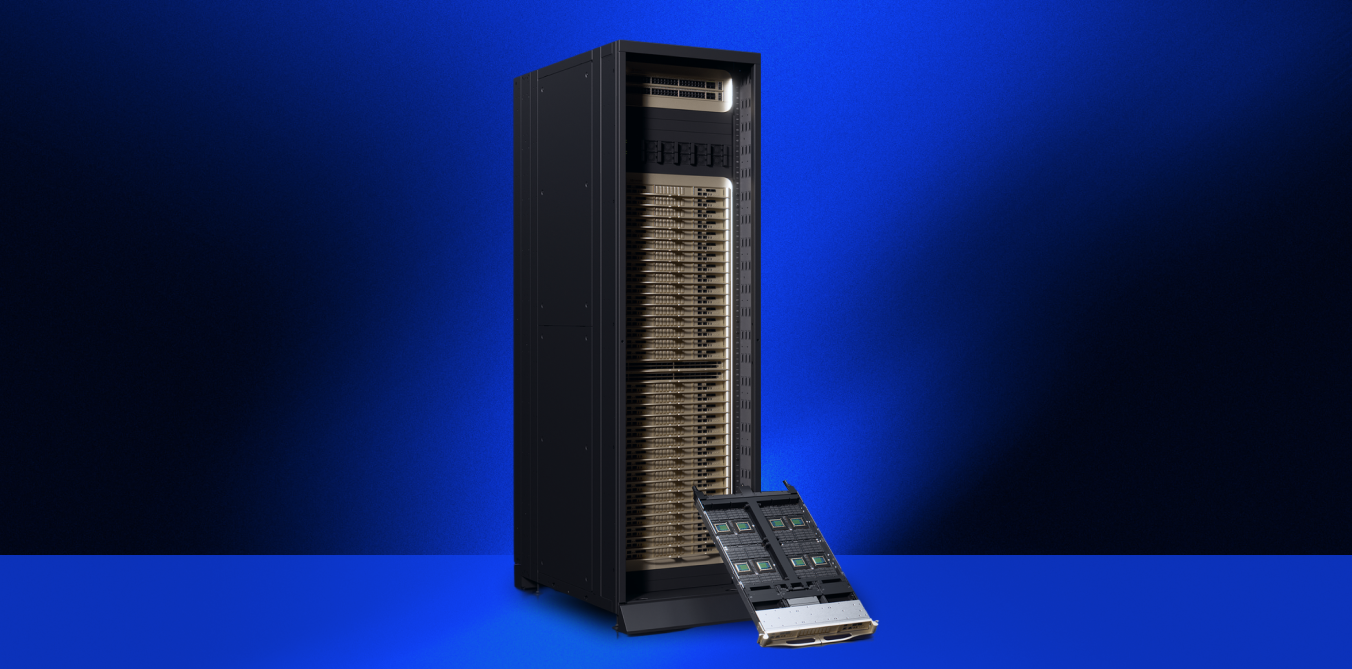
Nscale has brought its first NVIDIA Vera Rubin NVL72 rack-scale supercomputers online, the start of a worldwide deployment that is expected to continue in the coming months. Built on Dell PowerEdge XE9812 systems, the new infrastructure is integrated with Nscale’s cloud control plane, fleet automation, observability capabilities, and RoCE backend network. Customers will use this infrastructure to train the next generation of frontier models, run larger and more complex reasoning workloads, and serve inference at higher token throughput.
NVIDIA Vera Rubin NVL72 brings NVIDIA’s latest GPU, CPU, NVIDIA NVLink, NVIDIA Spectrum-X Ethernet networking, and infrastructure technologies together as one rack-scale AI supercomputer. The platform is built for the workloads now driving demand for compute: large distributed training runs, long-context reasoning, reinforcement learning, agentic inference, and AI services that need to generate and process large volumes of tokens at low latency.
Nscale is also the first in the industry to deploy Dell’s fully integrated, liquid-cooled L11 network rack. Built on the Dell IR9148 platform, the rack combines eight NVIDIA SN6600-LD switches with shuffle boxes, power shelves, an integrated rack controller and an in-rack coolant distribution unit. The system is factory-integrated and tested for shipment fully populated, eliminating onsite network rack assembly and reducing deployment time.
Connecting racks into one production cluster
Over the coming months, Nscale is expected to continue a global rollout as one production environment.
Running these GPUs as one environment depends on the whole system as much as the accelerator. NVIDIA NVLink creates a high-bandwidth scale-up fabric within each Vera Rubin NVL72 rack. A RoCE scale-out network (such as NVIDIA Spectrum-X Ethernet) connects those racks into a large-scale cluster, carrying the distributed training and inference traffic that lets many GPUs work together. The architecture is designed to keep GPUs productive across large, highly parallel workloads rather than leaving compute waiting on memory, networking, or operational bottlenecks.
RoCE, or RDMA over Converged Ethernet, provides the high-throughput, low-latency communication required for this type of distributed AI infrastructure. Nscale is building a purpose-designed AI Ethernet fabric that brings together high-performance switching, congestion management, telemetry, and automation. The fabric is designed to deliver the performance that demanding AI workloads require on a standards-based Ethernet foundation built for global cloud infrastructure. The NVIDIA Spectrum-X Ethernet platform provides the technologies that make this class of AI fabric possible.
From rack-scale hardware to cloud capacity
The NVIDIA Vera Rubin NVL72 racks are part of Nscale’s cloud from the moment they come online. Nscale’s Fleet Operations platform manages the full lifecycle of every system, from initial enrollment and configuration through validation, burn-in, network integration, maintenance, repair, and retirement. Control Center applies the required software, firmware, network, and security baselines, then brings validated systems into service through a consistent, automated process.
Nscale’s observability capabilities provide a live view of the health and performance of the entire platform across compute, networking, storage, and orchestration. They connect infrastructure telemetry with automated operational response, helping Nscale identify issues early, maintain cluster performance, and keep capacity available as the fleet grows. Radar API exposes the signals customers need to operate against the platform, including availability, maintenance, repair status, device state, capacity, and other operational events.
Together, these systems let Nscale bring new Vera Rubin capacity into service consistently. Customers get that capacity with the automation, visibility, and operational model required to run it in production.
Built for reasoning and agentic workloads
Training runs are larger, models are more capable, and inference is becoming a major driver of compute demand. Reasoning models and agentic systems consume far more tokens than earlier AI applications, which increases the value of infrastructure that delivers high throughput while using power, networking, and compute efficiently.
NVIDIA Vera Rubin NVL72 gives Nscale a new foundation for that work. The platform is designed for a significant step up in AI training performance and inference token throughput. Nscale combines that rack-scale performance with a cluster architecture, cloud platform, and operational system designed to put that infrastructure to work for customers at global scale.
The first systems are now live, with further deployments planned over the coming months. Interested in learning more? Speak to Nscale to place an order or discuss deployment timelines.