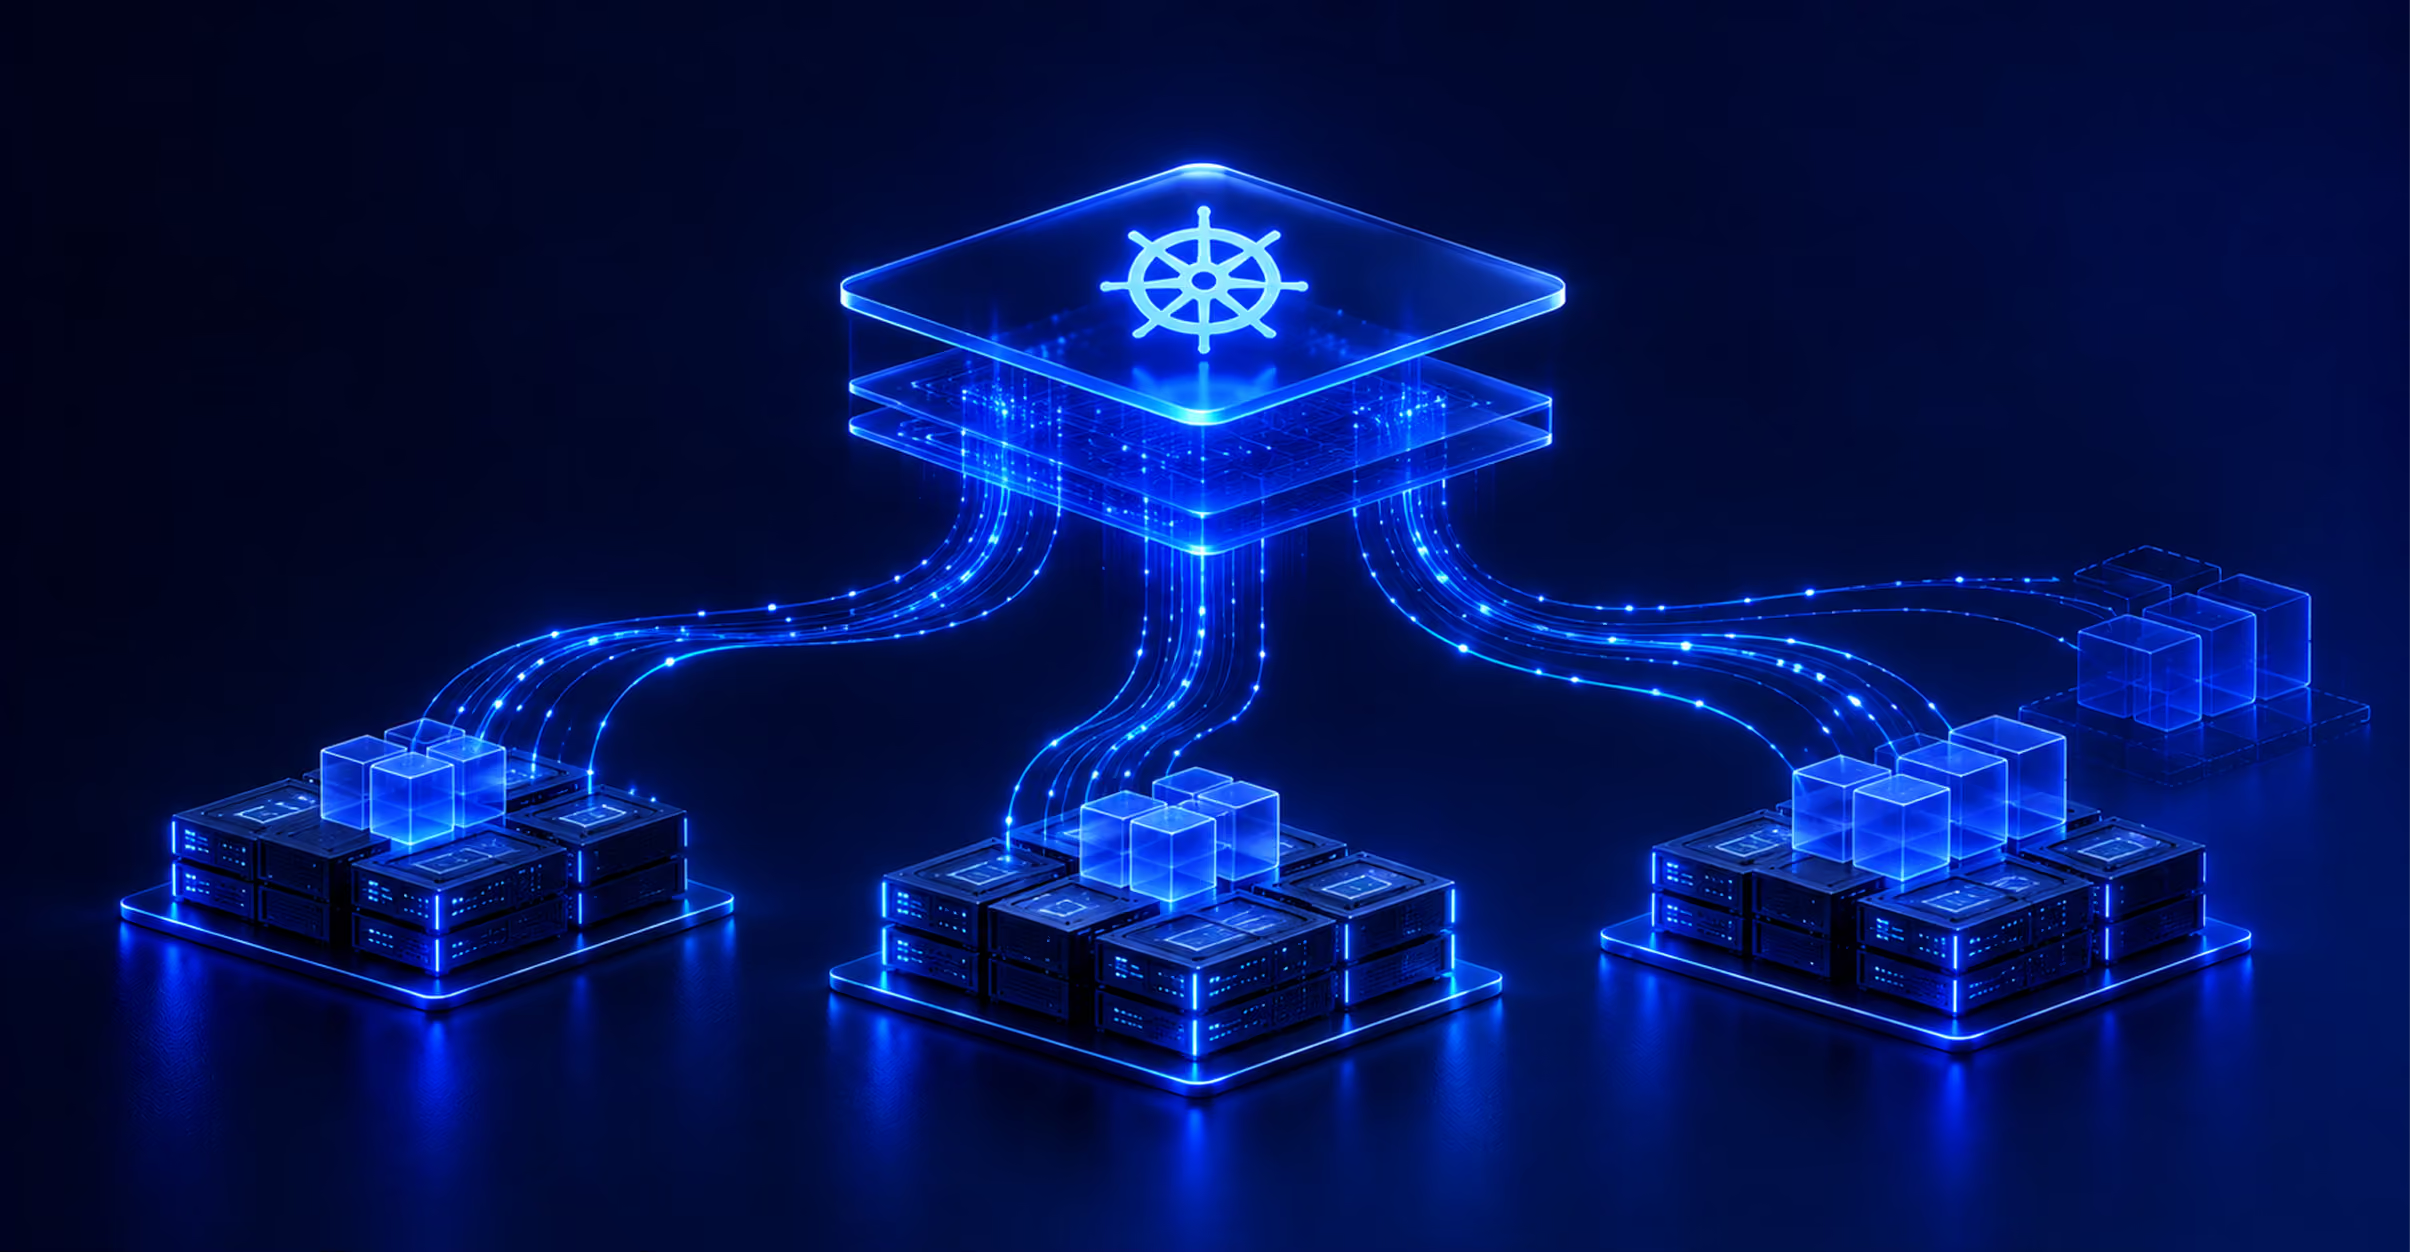
AI teams keep control of the application and compute while Nscale takes care of the serving layer.
Serverless inference is an important starting point for AI teams. Users can call a supported model through an endpoint and pay for what they use. For prototypes, internal tools, and workloads with variable traffic, that is usually the right fit.
Production inference brings a different set of requirements. Teams may need dedicated GPUs rather than shared capacity, single-tenant nodes to support data sovereignty, predictable performance for mission-critical systems, and a clear visibility into utilization and cost. Ultimately, they want inference to run on infrastructure they control.
Nscale Dedicated Inference on Nscale Cloud enables customers to take a supported model from the catalog, deploy it on the Nscale GPU capacity they have reserved, and access managed endpoints for production inference. Your team keeps the application and the dedicated compute, while Nscale manages the serving layer underneath.
Today, available models include NVIDIA Nemotron 3.5 Super VL, GLM 5.3, GLM 5.2-FP8 and DeepSeekv4-Flash.
What changes when inference becomes a product
Moving a model from a shared endpoint to dedicated GPUs changes what the team is responsible for. In a serverless model, the serving layer is largely invisible. With many providers, dedicated capacity means someone has to own Kubernetes, the serving engine, routing, model storage, and GPU operations, and keep them tuned, upgraded, and available. Reserving the GPUs is the first step; running the serving stack reliably and efficiently in production is the operational challenge Nscale is built to handle.
We support teams in three ways: helping them deploy faster, providing comprehensive observability, and reducing lifecycle work.
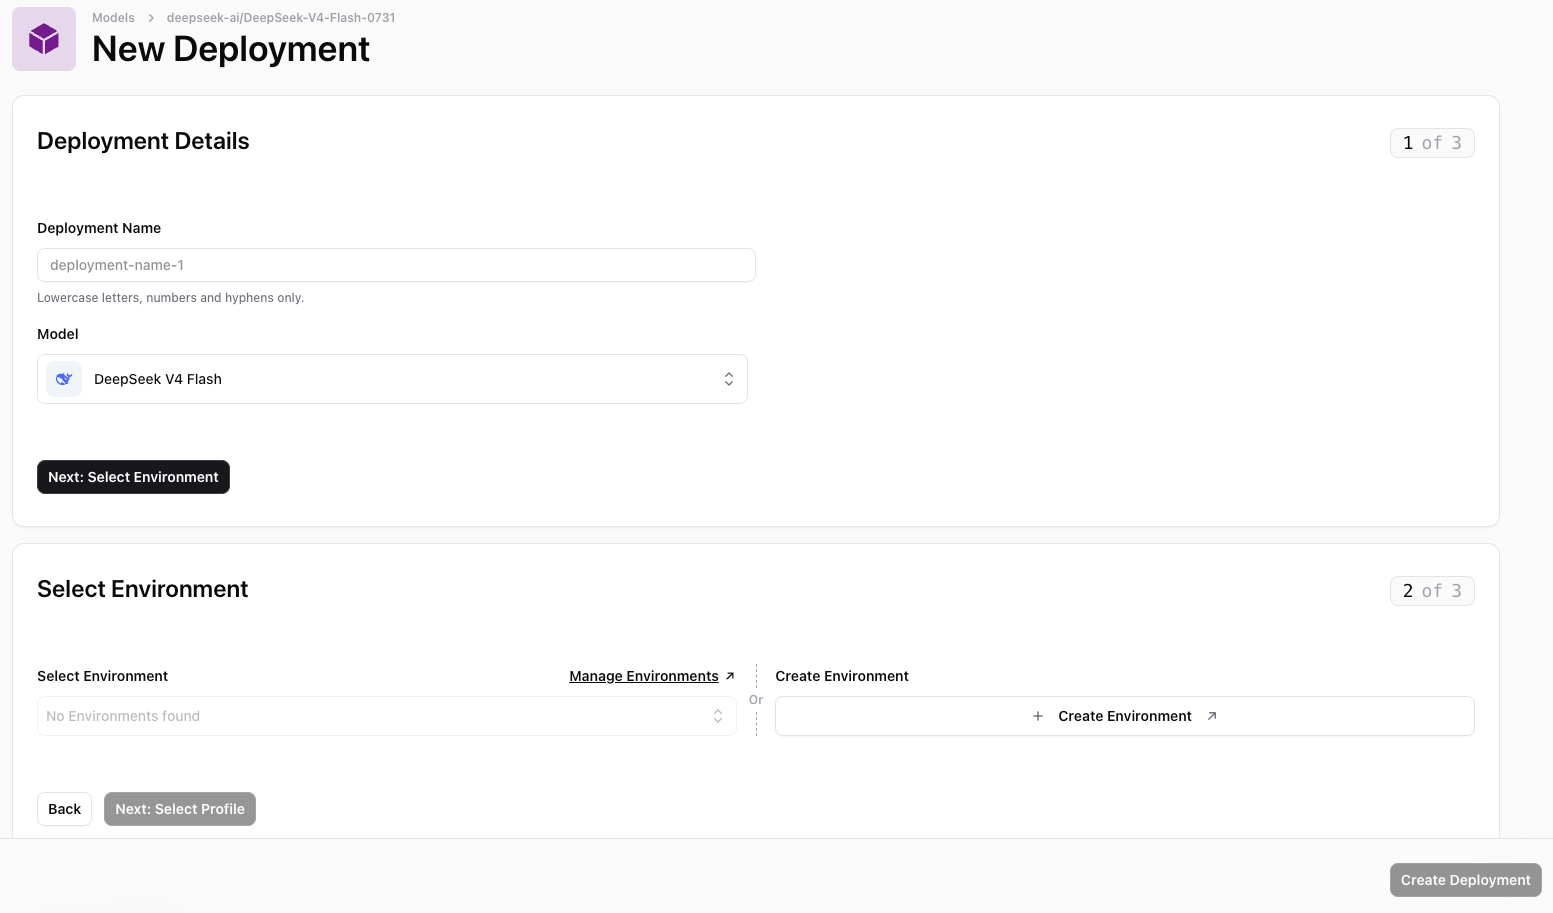
From supported model to production endpoint, faster
Most of the time to production goes into what surrounds the model: standing up Kubernetes, choosing and tuning a serving engine, wiring routing and model storage, and getting GPU operations to a state you would trust in production. Each of those pieces has to be assembled, and then made to work with the others.
With Nscale Dedicated Inference, that foundation is already in place. You start with a supported model from the model catalog and the Nscale GPU capacity reserved for your workload. Nscale deploys the model into your managed Nscale Cloud environment using hardware-aware deployment profiles designed for that model and accelerator, and hands you an endpoint to connect to your application.
Because compute, networking, storage, orchestration, inference services, observability, and identity and access management (IAM) are engineered to work together, the path from model to endpoint can be shortened, helping speed up troubleshooting and keeping your GPUs running more efficiently.
Full-stack ownership means one accountable partner
When inference spans a GPU provider, a serving platform, and separate internal tooling, a latency spike or a failed rollout can become a question of ownership. Each party may have visibility into its own layer and not much else.
Nscale owns and operates every layer of the inference path, from the underlying power and GPU infrastructure up to the model-serving layer. That gives us full-stack observability: we can see the complete path a request takes, optimize it end-to-end, and remediate issues wherever they occur, rather than stopping at a vendor boundary that teams often have with other providers.
For customers, that translates into more predictable performance, higher availability, better token economics, and one partner accountable for the outcome. Inference is managed alongside your models, environments, and dedicated capacity, so your team gets a single view of reliability, utilization, and production costs within one Nscale Cloud operating model.
Nscale manages the serving lifecycle
Deploying a model once is the easy part. Keeping it in production means monitoring it, upgrading the serving stack without disrupting workloads, and having a rollback path ready when an upgrade does not behave as expected. For many teams, that is a standing operational commitment, rather than work that directly creates value for their customers.
Nscale Dedicated Inference manages the full-stack lifecycle: deployment, monitoring, upgrades, and rollback paths, along with the endpoint lifecycle and the serving machinery underneath it. Because Nscale has visibility across the whole stack, time to resolution is shorter when something does go wrong. Your team stays in control of the application and the dedicated compute. Nscale takes on the serving operations beneath them, so engineering time goes into building AI products rather than running model-serving infrastructure.
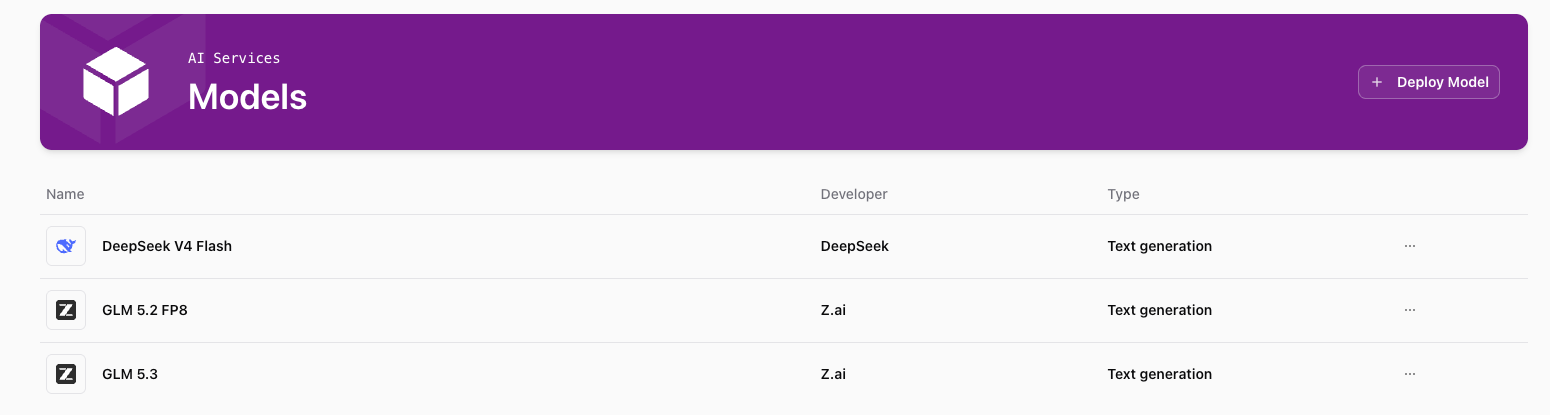
How it works
- Choose your model: Start with a supported model from our model catalog and the Nscale GPU capacity reserved for your workload.
- Deploy with an Nscale profile: Deploy the model into your managed cloud environment using one of Nscale's hardware-aware deployment profiles, pre-defined for the model and accelerator. Choose the profile that fits your reserved capacity.
- Connect your application: Connect through a managed endpoint while Nscale manages the serving machinery and endpoint lifecycle underneath it.
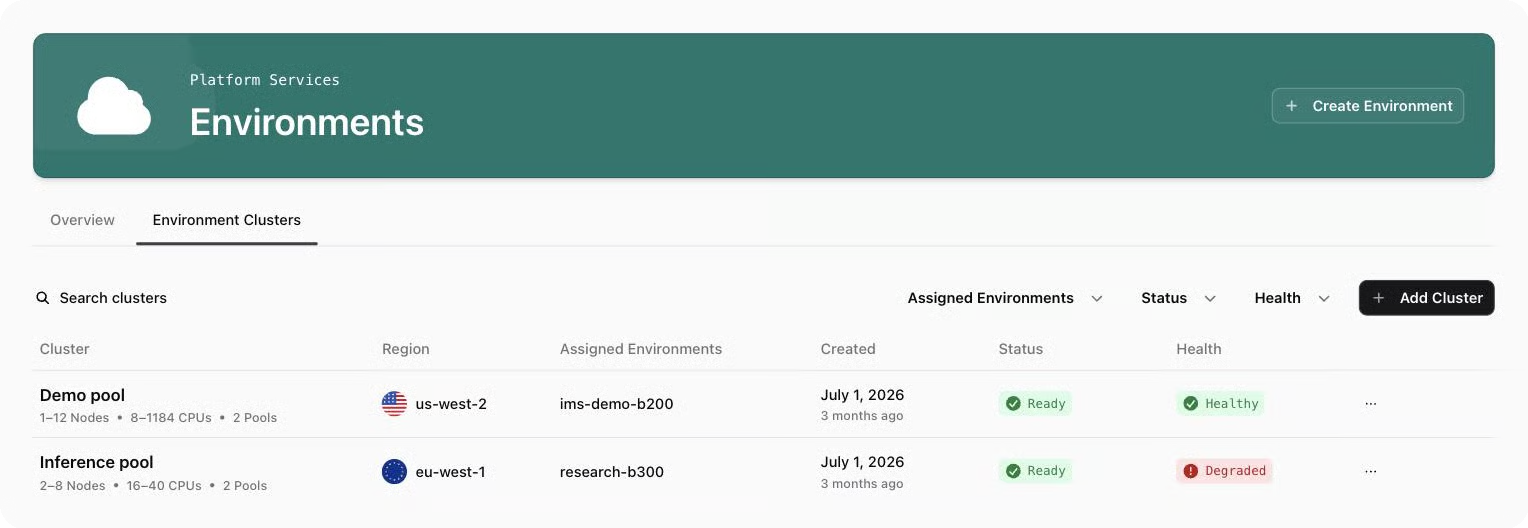
Built for teams taking inference into production
Nscale Dedicated Inference is built for AI Natives, enterprises, and the developers behind them who need dedicated inference capacity and predictable production operations. It removes the need for infrastructure teams to build and maintain model serving as another platform.
AI Natives get a fast path from training to production on contiguous infrastructure, without taking on the operational burden that usually comes with it.
Enterprises get single-tenant GPU nodes to support data sovereignty for mission-critical AI systems, without investing in bespoke infrastructure.
Developers get features that work with the tools and models they already use, reducing context-switching and keeping workflows simple.
Serverless to get started. Dedicated to run at scale.
Nscale Serverless Inference remains the fastest way to try a model on Nscale. When production requires consistent latency, enhanced control, and more manageable costs, Nscale Dedicated Inference gives your team production endpoints on Nscale’s capacity, while you maintain control.
Ready to elevate your production inference on dedicated Nscale GPUs? Explore our Dedicated Inference page to discover how reserving dedicated GPU capacity can transform your AI workloads.